Caching and CDNs: why the second load is instant
How Cache-Control headers control browser caching, what a CDN actually does, and why cache invalidation is one of the two hard problems in computing.

The first time you load a big website, it takes a second or two. Reload it a moment later and it's nearly instant, often without a single visible network request in the waterfall. Nothing about the site got faster in between. What happened is that most of it never left your machine the second time. This lesson is about the two layers that make that possible: caching, and the network of servers, CDNs, that make caching work at a global scale.
Cache-Control: the header doing the real work
Every response mentioned in lesson 6 can carry a Cache-Control header telling the browser (and anything else sitting between it and the server) how long it's allowed to reuse this response without asking again.
HTTP/1.1 200 OK
Cache-Control: public, max-age=31536000, immutable
Content-Type: application/javascript
max-age=31536000 means: this response is good for a year, don't even bother checking back. public means shared caches (like a CDN) can store it too, not just this one browser. immutable tells the browser it doesn't even need to revalidate on a hard refresh, because this exact file will never change. That combination is common on bundled JavaScript and CSS files that ship with a content hash in the filename, app.a3f91c.js. If the file's contents ever change, the build produces a new filename, so caching the old one forever is completely safe. The old URL simply stops being referenced.
Compare that to a response for something that changes often:
Cache-Control: no-cacheno-cache doesn't actually mean "don't cache," despite the name. It means "cache it, but check back with the server before reusing it." The server can then reply with a lightweight 304 Not Modified if nothing's changed, skipping the cost of re-sending the whole body while still confirming freshness. no-store is the header that means what "no-cache" sounds like: don't cache this at all, common on responses containing sensitive account data.
See it happen right now
Open dev tools, go to the Network tab, and reload any site twice. On the second load, look at the Size column. Entries showing "(disk cache)" or "(memory cache)" instead of a byte count never touched the network. That's Cache-Control doing exactly what it says.
Where caching happens between you and the server
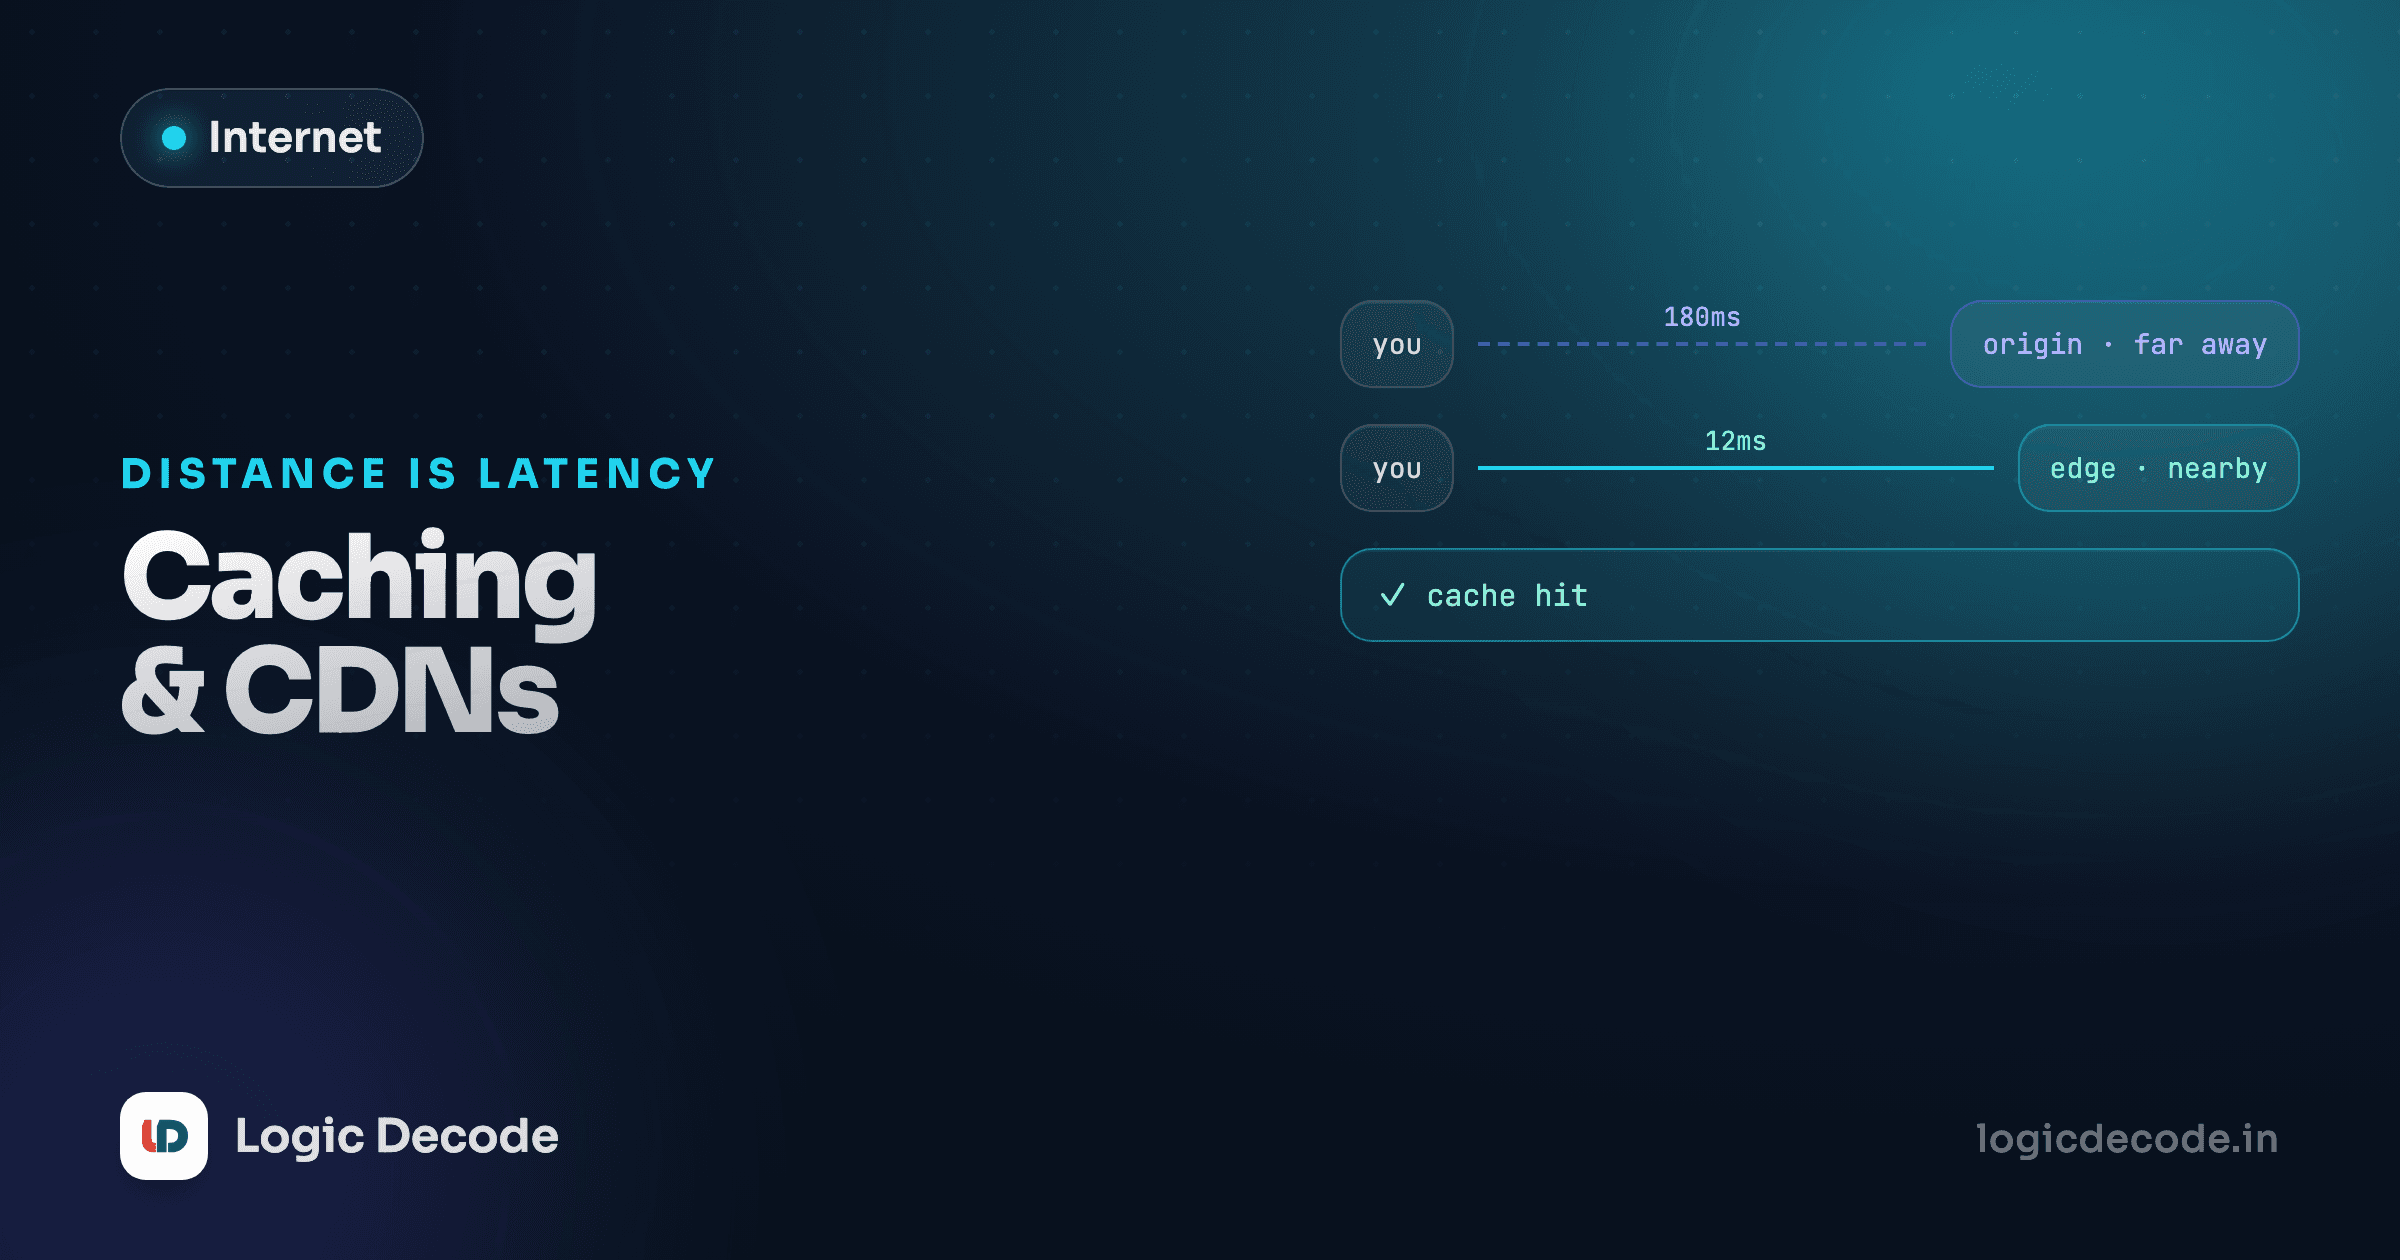
The browser cache is one layer, but it's not the only one, and it's not even the first one that matters for most real traffic. A request from Sam in Mumbai to a server in Virginia has to cross the actual physical distance between them, and light in fiber only travels so fast. That trip alone can cost 150 to 200 milliseconds each way, before the server has done any work at all.
A CDN, Content Delivery Network, solves this by putting copies of cacheable content on servers physically distributed around the world, so a request gets served from a location near the requester instead of crossing an ocean every time.
The first request for a given file from a given region is a cache miss: the edge server nearest that user doesn't have it yet, so it fetches from the origin server once, stores a copy, and serves it. Every subsequent request from anyone near that same edge server is a cache hit, served locally, no trip back to the origin at all. This is why the same site can feel instant for one visitor and noticeably slower for another, they may be hitting an edge server that's already warm versus one seeing that file for the first time.
The hard part: invalidation
There's an old joke in computing that there are only two hard problems: cache invalidation, naming things, and off-by-one errors. It's a joke about the count being wrong on purpose, but the caching part is genuinely the real difficulty. Caching itself is easy: store a copy, serve it again. The hard part is knowing exactly when that copy has gone stale and needs to be thrown out.
Get the max-age too long on content that changes, and users see outdated data for longer than intended, a stale price, an old headline, a promotion that already ended. Get it too short, and you lose most of the benefit caching was supposed to give you, hitting the origin server constantly for content that rarely changes. This is exactly why the content-hash trick from earlier is so popular for static assets: it turns "when should this expire" into "this URL is a completely different file the moment the content changes," which sidesteps the invalidation problem instead of solving it.
Quick check
A site's build system names its JavaScript bundle app.a3f91c.js, where a3f91c is a hash of the file's contents, and serves it with Cache-Control: max-age=31536000, immutable. Why is this safe even though the cache lasts a full year?
What this buys you as a developer
Understanding this layer explains two very different-feeling bugs. "I pushed a fix and it's still showing the old version" is almost always a caching problem somewhere in this chain, not a broken deploy, check the response headers before assuming the code didn't ship. And "why is my API slow for some users but not others" often traces back to CDN edge locations and whether a particular response was even eligible to be cached in the first place, since dynamic, personalized responses (an authenticated dashboard, in particular) usually shouldn't be cached at all, and forcing them to be is how session data leaks between users who happen to hit the same edge cache entry.
You've now covered every layer this series set out to teach: DNS, IP and packets, TCP and UDP, HTTP, TLS, HTTP/2 and HTTP/3, cookies, CORS, and caching. The last lesson puts all of it together with real tools. On to Project: trace a real request end to end.
Written by
Rhythm Bhiwani
Engineer and relentless builder, happiest reverse-engineering hard problems until they click.
Enjoyed this?
Tap the heart to leave some love.
Be the first to react
Comments
Join the conversation.
Loading comments…